How to Trace a Webhook From Sender to Handler in Production
Follow webhooks past HTTP 200 to see if the business outcome actually happened.
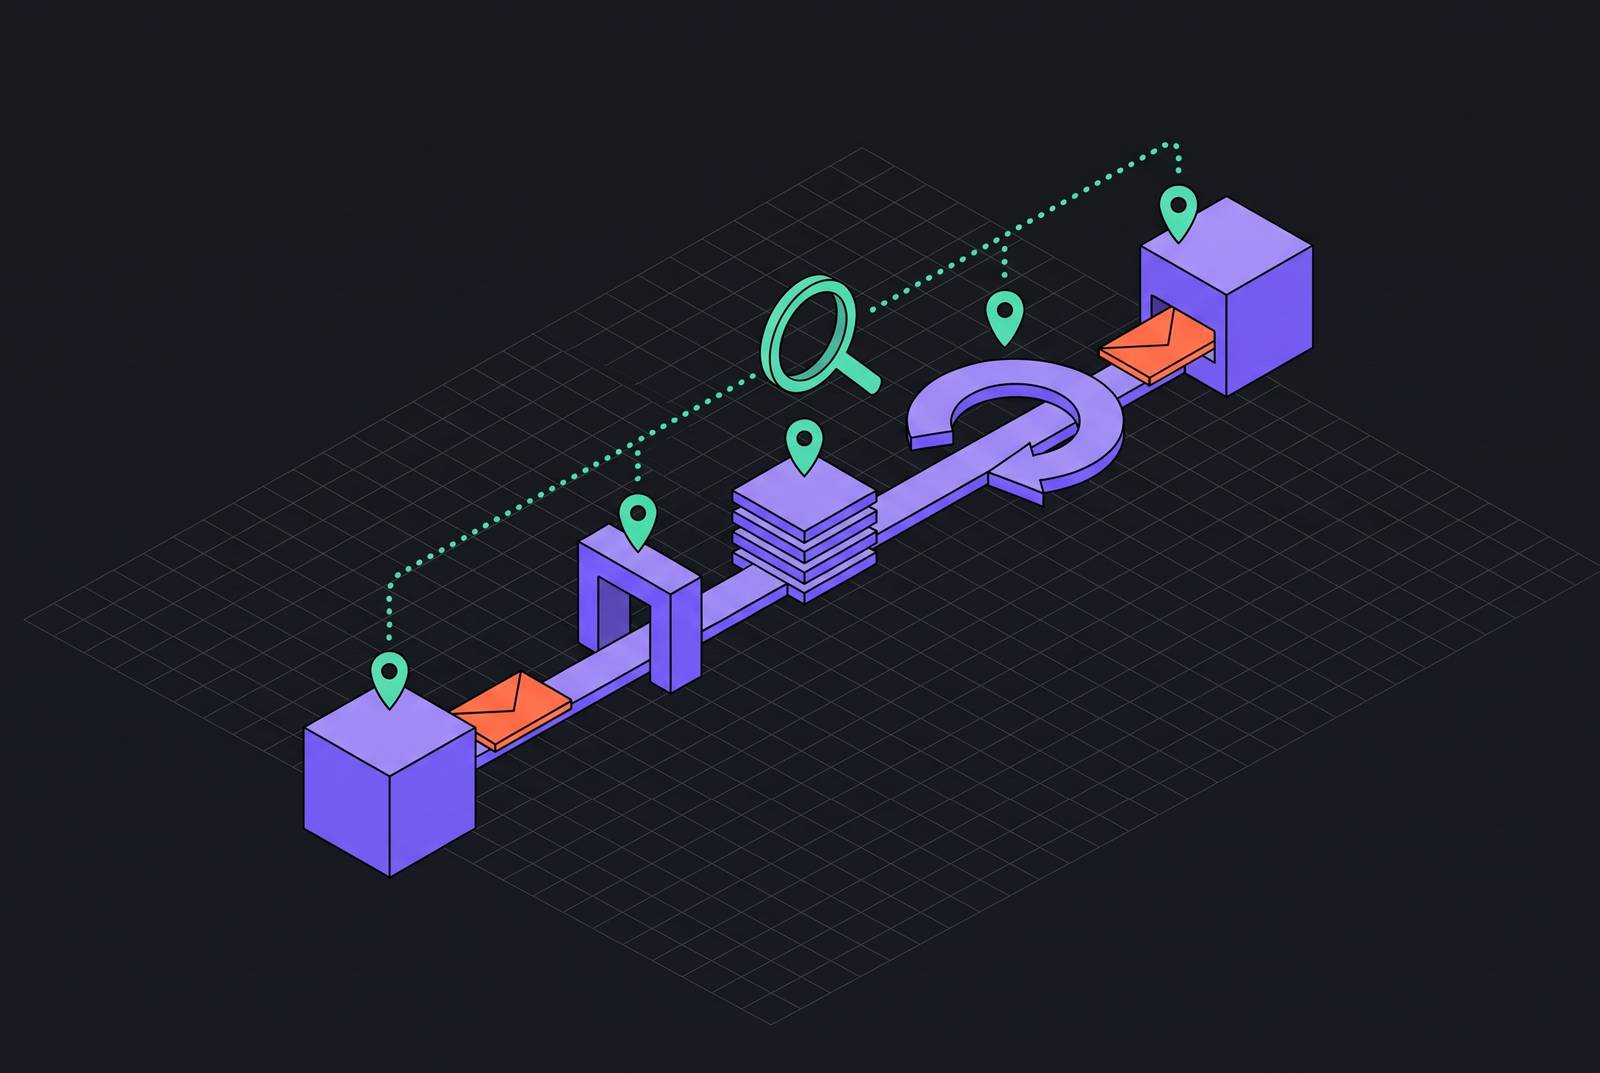
Tracing a webhook from sender to handler in production means following it past the HTTP response to the business result. That requires treating ingestion and processing as separate observability problems, then joining them with correlation IDs, structured logs, and handler spans. HTTP 200 confirms receipt.
Why a webhook trace that stops at HTTP 200 is not a trace at all
A customer opens a support ticket days after a dropped renewal event. The endpoint returned 200, the dashboard stayed green, and the account never updated. The customer has become the monitoring system. That is an expensive way to discover a missing handler outcome, especially when the delivery record looks successful.
The blind spot starts at the organizational boundary. Your APM trace begins when the request reaches your endpoint, leaving the sender’s scheduling, batching, and retry behavior upstream. A handler crash after acknowledgment can look healthy to external systems and HTTP error dashboards. Conversely, a provider-disabled endpoint or a firewall dropping traffic leaves no local errors at all.
A complete delivery history therefore needs evidence of ingestion, routing and transformation, and every delivery attempt, including status, latency, and retry state. Those stages expose different failures.
The ingest leg: what must be captured before the handler runs
Ingest evidence must survive a handler failure. The capture layer needs to record what arrived independently of whether processing succeeds, rather than leaving that record inside code that may crash. An inspection endpoint can provide that separation. A second registered URL is another option where the provider supports it.
Correct logging begins with the verification order. Verify the HMAC-SHA256 signature against the raw request body using a constant-time comparison and a timestamp replay window before reading or acting on payload fields. Until verification passes, an attacker can control even the event ID. Treating it as trusted because it looks familiar gives untrusted input a staff badge.
The ingest record should include arrival time, source, headers with sensitive values redacted, payload hash, and body size. Record only the signature header’s presence, and never log a raw body containing PII or credentials. Track acceptance, rejection, and discard counts separately by source. Rising rejections can signal a sender-side change, while accepted requests discarded by filters or deduplication need a different investigation. A schema change may be steering legitimate events into exclusion logic before a handler ever sees them.
How correlation IDs stitch the ingest and processing legs into one trace
A correlation ID provides the join across process boundaries. Without one, a 3 AM investigation becomes a manual match across four logs using timestamps and event IDs. Clocks make poor detective partners. The identifier gives every record for the operation a shared reference, including records produced after the HTTP request has ended.
OpenTelemetry context propagation bridges that asynchronous gap. The ingest layer stores the trace ID and span ID with the persisted event row in the queue. The delivery worker reads those IDs, reconstructs the remote span context, and then starts its child span.
Retries need both continuity and distinction. Every attempt shares the same correlation_id, but receives a unique delivery_id, making the delivery history reconstructable as a tree. Attaching the webhook event ID as a span attribute also connects a failed payment notification to the database timeout behind it. A unified backend containing user events, transactions, and webhook records makes that connection a direct query, eliminating the cross-system join and ETL hop.
What the processing leg must prove: handler instrumentation beyond status codes
Processing instrumentation must show when work has been durably accepted and when it is done. With status codes alone, a 200 followed by a dropped queue message looks identical to a 200 followed by a successful ledger write. The business operation needs evidence of completion beyond the response and the HTTP span.
The execution order makes that evidence honest. Verify the signature, deduplicate on event ID, persist the raw event to a durable queue, and then return 200 or 202 before processing in the background. Durable storage precedes acknowledgment. Otherwise, the response says the work was accepted before there is proof that it survived. Fast acknowledgment also avoids the case where successful but slow processing causes a provider timeout and another delivery.
Inside the worker, put span boundaries around the ledger write, fulfillment trigger, or account update itself. Explicit outcome logs should include the event ID, event type, signature verification result, first-seen or duplicate outcome, and final business outcome. The stored trace context links this worker span to ingestion. These records identify completed work.
Even the response path needs scrutiny. A load balancer health check using the webhook path can acknowledge requests before the application receives them, which calls for a dedicated health-check route and webhook traffic proxied only to the app server. Agent-driven workflows extend the same obligation. Trace IDs and structured logs must survive each hop so the record identifies the initiating event, data the agent saw, policy gate applied, and tool calls made.
Idempotency as a tracing dependency, not just a resilience feature
Three records saying invoice.paid processed for the same event ID expose a broken deduplication layer. Because webhook delivery is at least once, retries can bring the same event back repeatedly, especially after slow responses. A trace is trustworthy only if its business outcomes distinguish repeated delivery from repeated execution.
A database unique constraint makes that check atomic. The event-ID insert succeeds for a first arrival or violates the constraint for a duplicate, giving transactional operations a firm decision point. Redis SET NX with TTL is a fast pre-check for high-throughput streams where a database round-trip for each event costs too much. It cannot be the final authority for high-stakes billing, because eviction must not admit a duplicate during a billing-cycle close. The database constraint still has final say.
The choice is about throughput and consistency. Retention is part of that decision. A deduplication cache must last at least as long as the provider’s full retry window, or a late retry can arrive after its key expires and be recorded as fresh work.
The four signals that cover both sides of the pipeline
Freshness, status-code distribution, handler latency, and payload anomalies cover different gaps in the same pipeline. Freshness tracks how long it has been since the last event arrived and catches failures that leave no local error, including blocked traffic and disabled endpoints. Silence needs an alarm of its own. Alert when the gap exceeds the stream’s normal variance, because a payments integration quiet for an hour can be an incident despite an error count of zero.
A 404 can point to a route that moved or a reverse-proxy rule that changed, while 422 or 400 can point to a schema change or stricter validation. A 500 can point to handler code that failed after the request arrived. Separate buckets turn a generic failure alert into a useful starting point for the right owner.
Track p95 and p99 against the provider’s timeout budget. In an example scenario, a 3% payment delay rate was linked to a P99 latency spike because slow requests led to provider timeouts and retries. Alert at half the timeout budget. The durable remedy is immediate acknowledgment after queue persistence, with processing moved to the background.
Payload anomalies expose changes that code may quietly ignore. Watch for unknown event types that reach a catch-all branch, required fields that are missing, content types that were not expected, and body sizes that jump an order of magnitude. Unknown-type spikes can signal a new provider API version. Queue health supplements these four signals with pending depth and the age of the oldest pending event, showing both the scale of a backlog and how long work has waited.
What a real failure looks like traced end-to-end: the 2 AM body-parsing incident
In the 2 AM body-parsing incident, consumer logs captured 401 responses, but alerts watched for 500s. The working assumption was that a 401 meant an external sender had submitted a bad request. No page fired, and the failure persisted until morning.
An end-to-end view would have changed the investigation. Ingest records would have shown valid incoming payloads and rising 401s, while the correlation ID would have led to handler-side signature verification. That distinction places arrival and rejection in the same timeline without treating the HTTP response as the whole story. Instead of a 90-minute manual investigation, the joined record would have made the failure boundary plain.
The missing companion was freshness measured on business-outcome events. Arrival freshness alone could not establish that processing was succeeding while requests continued to reach the endpoint. Outcome freshness is the sharper catch because it watches for completed work.
Log hygiene, retention tiers, and GDPR obligations that shape what you can keep
Webhook logs create their own GDPR exposure because events may contain PII and financial data crossing geographic boundaries. The logging pipeline is itself a data processor. For teams implementing this trace, retention and redaction policies therefore belong before production.
Redact or entirely omit raw signing secrets, API keys, or authentication tokens from logs. For payloads, prefer hashes or truncated, redacted previews instead of full bodies by default, with field-level redaction for passwords, tokens, SSNs, and card numbers. Durable event storage is not permission to copy its contents into every log sink.
Retention should follow the record’s purpose. Keep delivery metadata for active debugging and analytics, and payload hashes for deduplication verification. Full payloads should be kept for a short time for active debugging only, then purged or archived as the policy requires. Error traces need to be kept longer so patterns can be found. Audit logs have the longest retention, driven by PCI-DSS, SOC 2, or sector-specific requirements.
Storage tiers can reflect those different windows. Hot storage holds recent records for live debugging, warm storage keeps them through the operational window, and cold archives keep them for as long as compliance requires. European hosting can simplify GDPR obligations by keeping the logging pipeline within the same regulatory boundary as an EU-hosted product. That reduces the separate work of documenting transfer mechanisms when log data would otherwise leave the EU.
Putting the full pipeline together: the instrumentation checklist by layer
Ingest. Set up capture independent of handler success through an inspection endpoint or a second URL where supported. Generate a correlation ID at arrival, and record timestamp, source, body hash, size, and event type only after verification permits reading it. Keep counters for acceptance, rejection, and discard for each source. Redact sensitive headers and payload fields.
Queue and context propagation. Persist the event before acknowledgment, with its trace ID and span ID. Have the worker reconstruct remote context before opening its child span. Preserve the correlation ID across retries. Give each attempt a unique delivery ID so repeated delivery remains visible without fragmenting the operation.
Handler. Return 200 or 202 after durable acceptance and process in the background. Instrument the business call, then log the deduplication decision and final outcome. Keep the deduplication TTL at least as long as the retry window, with database authority where required. Put load-balancer health checks on their own route.
Alerting. Use an alerting tool to track stream freshness through business-outcome events as well as arrivals. Route status-code buckets separately, set p95 and p99 alerts at half the provider’s timeout budget, and flag payload anomalies. Monitor queue depth and oldest pending work for workers falling behind. Keep these records joinable across layers so an alert leads to an event’s history.